The Rise of Native Audio Models in AI
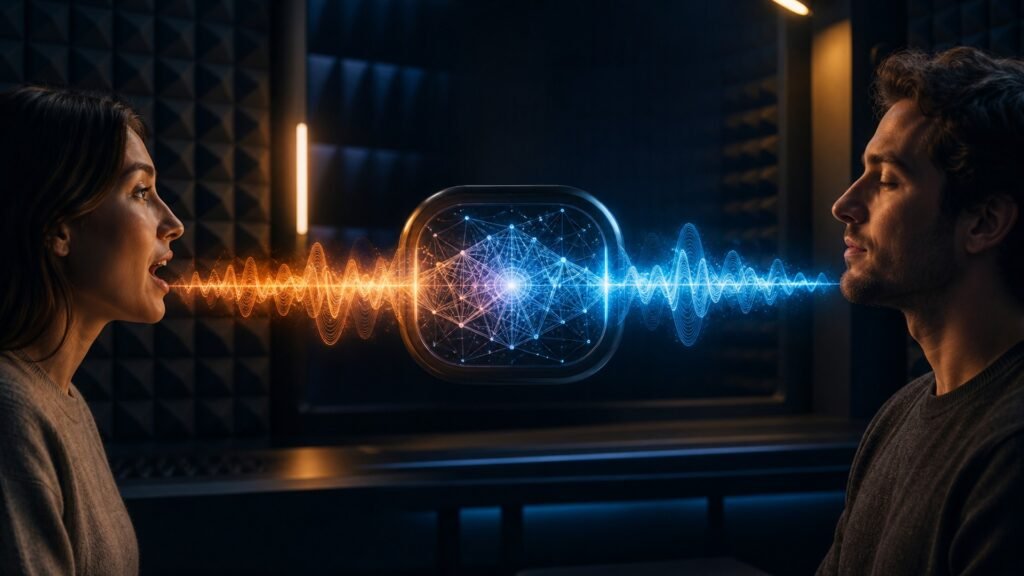
Recent technological developments in artificial intelligence highlight a shift toward native audio models that bypass traditional text transcription steps entirely. According to a report by Unite.ai, speech-to-speech systems are increasingly relying on architectures designed to process acoustic inputs directly. Traditional voice AI pipelines typically convert incoming audio into text using automatic speech recognition, process the text through a language model, and then synthesize a new audio output via text-to-speech engines. This multi-step process introduces latency and often strips away subtle emotional cues, acoustic nuances, and speaker intent present in human conversation.
By utilizing native audio frameworks, developers can create models that handle audio natively across the entire pipeline. This approach allows the system to comprehend tone, inflection, and pacing without requiring an intermediate textual translation layer. As these tools mature within the creative and communications sectors, they promise more natural conversational interfaces, improved real-time translation applications, and more expressive voice generation capabilities for media production.
Based on reporting by www.unite.ai.