Evaluating AI Protein Design Performance
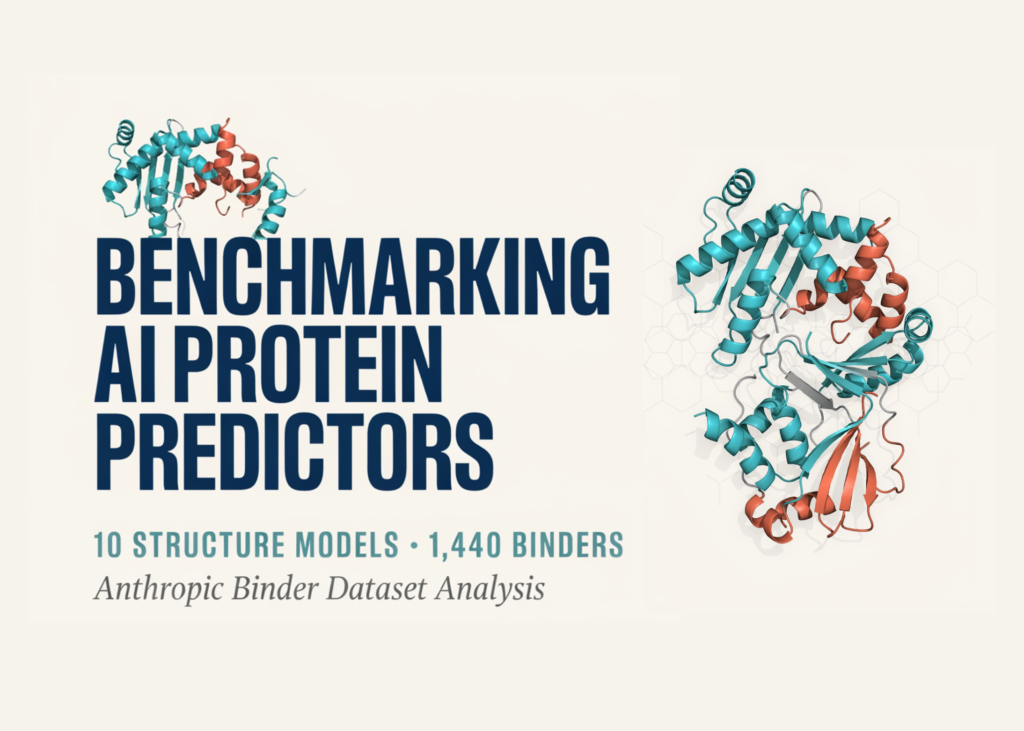
According to a report by MarkTechPost, researchers are increasingly focusing on the critical gap between computational predictions and physical laboratory execution in artificial intelligence protein design. While in-silico models have advanced rapidly in generating novel protein structures, evaluating their actual performance in real world wet-lab environments remains a significant challenge for the scientific community.
The evaluation initiatives aim to bridge the divide between theoretical computational success and practical biochemical viability. As machine learning models become central to synthetic biology and drug discovery, establishing standardized benchmarks for wet-lab validation is essential. Researchers note that generative models often produce sequences that look viable on computers but fail when synthesized physically due to folding instabilities, expression issues, or unexpected functional limitations.
MarkTechPost highlights that better integration of wet-lab feedback loops into training pipelines will help refine future iterations of protein generation software. By systematically comparing virtual metrics with physical laboratory outcomes, developers can improve the reliability and precision of AI tools designed for molecular biology and therapeutics development.
Based on reporting by www.marktechpost.com.