AudioShake Launches The Refinery for AI Audio Training
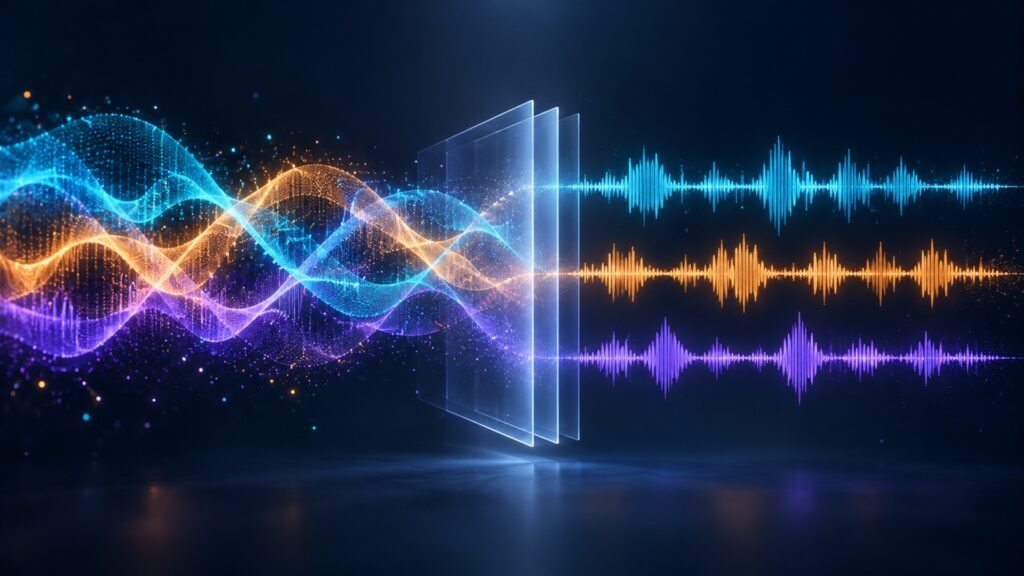
According to www.unite.ai, AudioShake has officially launched a new platform named The Refinery, aiming to address critical data bottlenecks in machine learning. The system is engineered to take complex audio files containing overlapping conversations and process them into clean, usable training datasets for artificial intelligence models.
Audio processing for generative models and conversational AI has historically struggled with multi-speaker crosstalk, where simultaneous voices obscure distinct linguistic patterns and speaker separation. The Refinery tackles this challenge by isolating individual streams from dense audio environments, supplying developers with high-fidelity datasets. This technological development serves the growing demand for specialized audio data capable of enhancing voice recognition applications, speech-to-text engines, and interactive conversational agents.
As the artificial intelligence industry continues to scale, the acquisition of clean and legally compliant training data remains a central priority for creators and enterprises alike. By turning messy real-world recordings into structured resources, AudioShake aims to bridge the gap between legacy audio archives and modern machine learning requirements.
Based on reporting by www.unite.ai.