BottleCap AI Launches ThinkingCap-Qwen3.8-27B Model
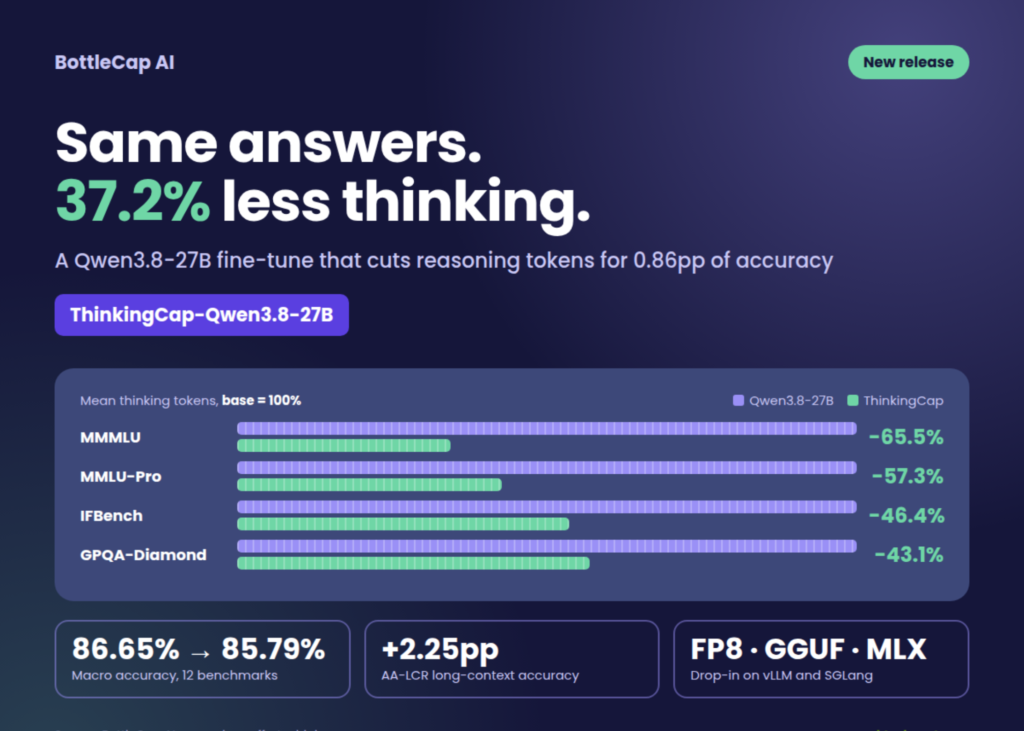
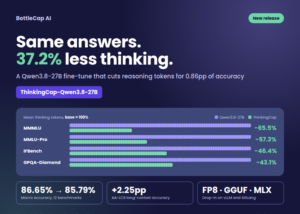
BottleCap AI has released a new open-weight model named ThinkingCap-Qwen3.8-27B, according to a recent report by MarkTechPost. The tool is designed to optimize reasoning processes in artificial intelligence applications by significantly reducing the volume of generated reasoning steps. According to the release details covered by MarkTechPost, the newly introduced architecture achieves 37.2 percent fewer thinking tokens compared to baseline configurations. This reduction in overhead comes with a minor trade-off, registering a minimal accuracy cost of only 0.86 percentage points.
The development addresses a major bottleneck in modern AI systems, where excessive reasoning token generation can inflate inference costs and increase latency for developers deploying large language models in production environments. By streamlining internal token usage during inference, the ThinkingCap-Qwen3.8-27B model aims to offer a more economically viable option for teams building agentic workflows and interactive web3 or AI applications. Industry observers note that efficiency improvements of this scale are critical for scaling resource-intensive reasoning models without sacrificing core task performance. Further technical specifications and deployment guidelines are available through BottleCap AI’s official developer channels.
Based on reporting by www.marktechpost.com.