OpenAI to Honor Shared Robots.txt Signals

According to reporting by Unite.ai, OpenAI has announced it will respect shared robots.txt signals regarding artificial intelligence training preferences. The decision addresses growing industry discussions concerning web scraping, content ownership, and how digital publishers control access to their online material for machine learning applications.
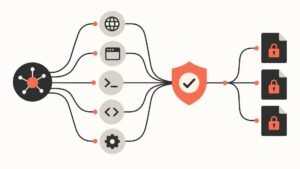
By honoring standardized robots.txt configurations, website administrators and content creators gain a clearer mechanism to communicate whether their publicly available data can be utilized for training large language models. The move aligns with broader technical developments aimed at establishing transparent boundaries between automated web crawlers and proprietary digital platforms.
As artificial intelligence developers face increasing scrutiny over data collection practices, implementing standardized signals offers a pragmatic path toward balancing open web indexing with publisher autonomy. The adoption of these shared protocols highlights an ongoing shift within the artificial intelligence sector toward more cooperative frameworks for data governance, ensuring that webmasters retain functional oversight of their digital assets across different crawling systems.
Based on reporting by www.unite.ai.