Google AI Releases Gemini 3.5 Transcribe
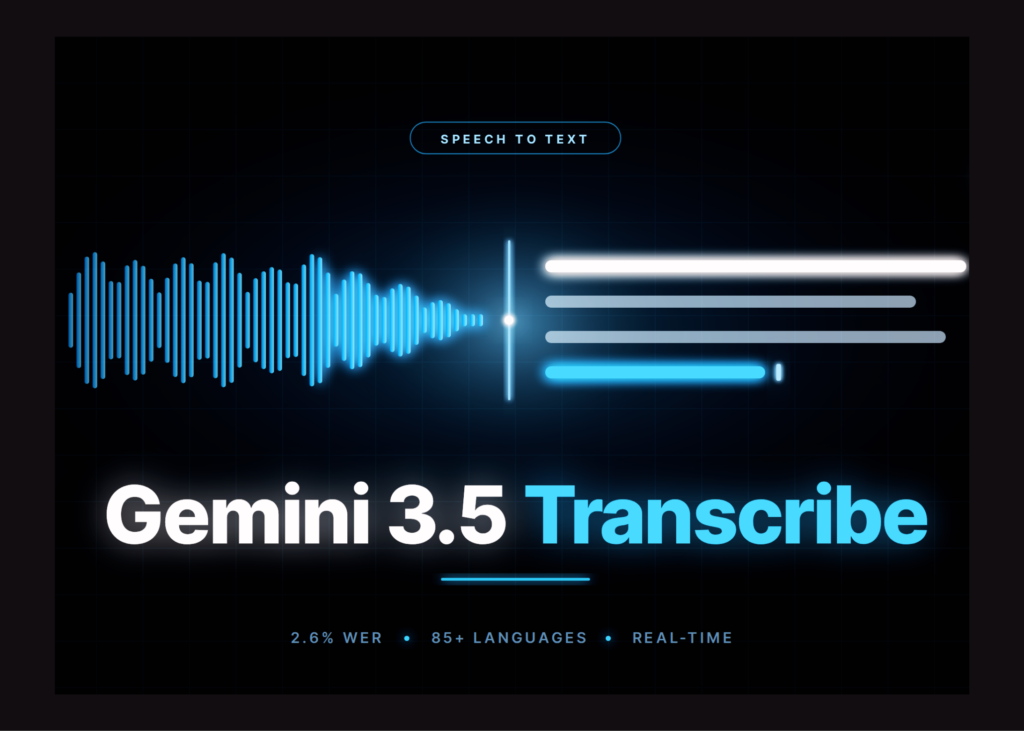
Google AI has officially released Gemini 3.5 Transcribe, a new speech-to-text model designed to handle audio processing across a wide array of languages. According to reporting by MarkTechPost, the newly introduced system achieves an average word error rate of 2.6 percent across more than 85 languages.
The deployment of Gemini 3.5 Transcribe addresses ongoing industry demand for highly accurate multilingual transcription tools. By lowering error rates in diverse linguistic environments, the model aims to improve automated captioning, voice assistants, and enterprise transcription workflows. Developers and enterprise users can integrate the speech-to-text capabilities into various consumer products and software applications to streamline audio data processing.
As competition intensifies within the AI tools and applications sector, major technology firms continue to refine foundational audio architectures. Google AI positions this release as a step forward in bridging accuracy gaps across low-resource and high-resource languages alike. Further details regarding API access, pricing tiers, and specific platform integrations are expected to roll out as the software becomes widely available to developers.
Based on reporting by www.marktechpost.com.